Bayanat Labs press kit
Everything you need to write about Bayanat Labs and our research: a boilerplate, key facts, the LabelBench findings, charts and logos. For interviews and data questions, email hello@bayanatlabs.com.
About Bayanat Labs
Short boilerplate. Bayanat Labs is a Riyadh-based Arabic AI data company. It licenses ready-made Arabic speech and text datasets, and sources, annotates, aligns and evaluates Arabic data across 25+ dialects: text, speech, image and video. Every label Bayanat produces comes from vetted native speakers and domain experts, is measured against gold standards, and is hosted in-region by default.
Long boilerplate. Bayanat Labs builds the human data that makes Arabic AI work. The company does data only and is model-agnostic: dialect-aware annotation, human feedback and RLHF, domain-expert data (medical, legal, financial), and independent Arabic LLM and agent evaluation. The work is done by vetted native speakers and licensed professionals across 25+ Arabic varieties. Contributors pass dialect and domain screening, work is calibrated against gold standards, and every task is adjudicated and audited. Data is hosted in-region by default, with on-prem and private-cloud options. Its catalog has nine product families: Voice, Voice Studio and Knowledge offer ready-to-license collections, including two separate 1,000-hour Saudi speech collections, 2,700 Arabic books and 400,000 STEM questions; Align, Agents and Bench add alignment, agent and evaluation data; Documents, Search and Vision are built to order. Its open research includes LabelBench, an audit of whether AI can label Arabic data.
Key facts
| Name | Bayanat Labs (please use the full name; “Bayanat” alone refers to other organisations) |
| Headquarters | Riyadh, Saudi Arabia |
| What we do | Arabic AI training data and evaluation: ready-to-license Arabic datasets, data sourcing, annotation and labeling, human feedback (RLHF), domain-expert data, LLM and agent evaluation, red-teaming |
| Products | Nine product families: Voice, Voice Studio, Knowledge, Align, Agents, Bench, Documents, Search and Vision. Arabic: منتجات Bayanat |
| Coverage | 25+ Arabic varieties; text, speech, image and video |
| Data handling | In-region by default; on-prem and private-cloud options |
| Research | LabelBench (July 2026) and the Arabic Agent Reliability Lab (methods beta) |
| Website | www.bayanatlabs.com |
| linkedin.com/company/bayanat-labs | |
| GitHub | github.com/Bayanat-Labs |
| Media contact | hello@bayanatlabs.com |
LabelBench in four numbers
LabelBench asks when Arabic labeling can safely move from people to models. We ran one fixed zero-shot rubric on identical held-out samples and compared the models with small supervised baselines.
- 78% → 25.3%. A local language model (Qwen 2.5 3B) scored 78% on binary Arabic toxicity. On the real seven-label taxonomy, exact-match accuracy fell to 25.3% on the fixed held-out manifest.
- 22.4%, where chance is 20%. The same model reached 22.4% when asked to identify five Arabic dialect regions.
- 75% of Gulf examples labeled Egyptian. Its errors were not random: it labeled 70–80% of each non-Egyptian region's examples as Egyptian.
- Specialization and native data help. Arabic-specialized Fanar 1 9B did better on all three tasks (47.8% on dialect region), and a character n-gram model trained on 100 examples per region reached 69.8%.
The paper, results (CSV and JSON) and checksums are public, and the code is on GitHub and on PyPI; see how to cite or embed LabelBench.
Charts
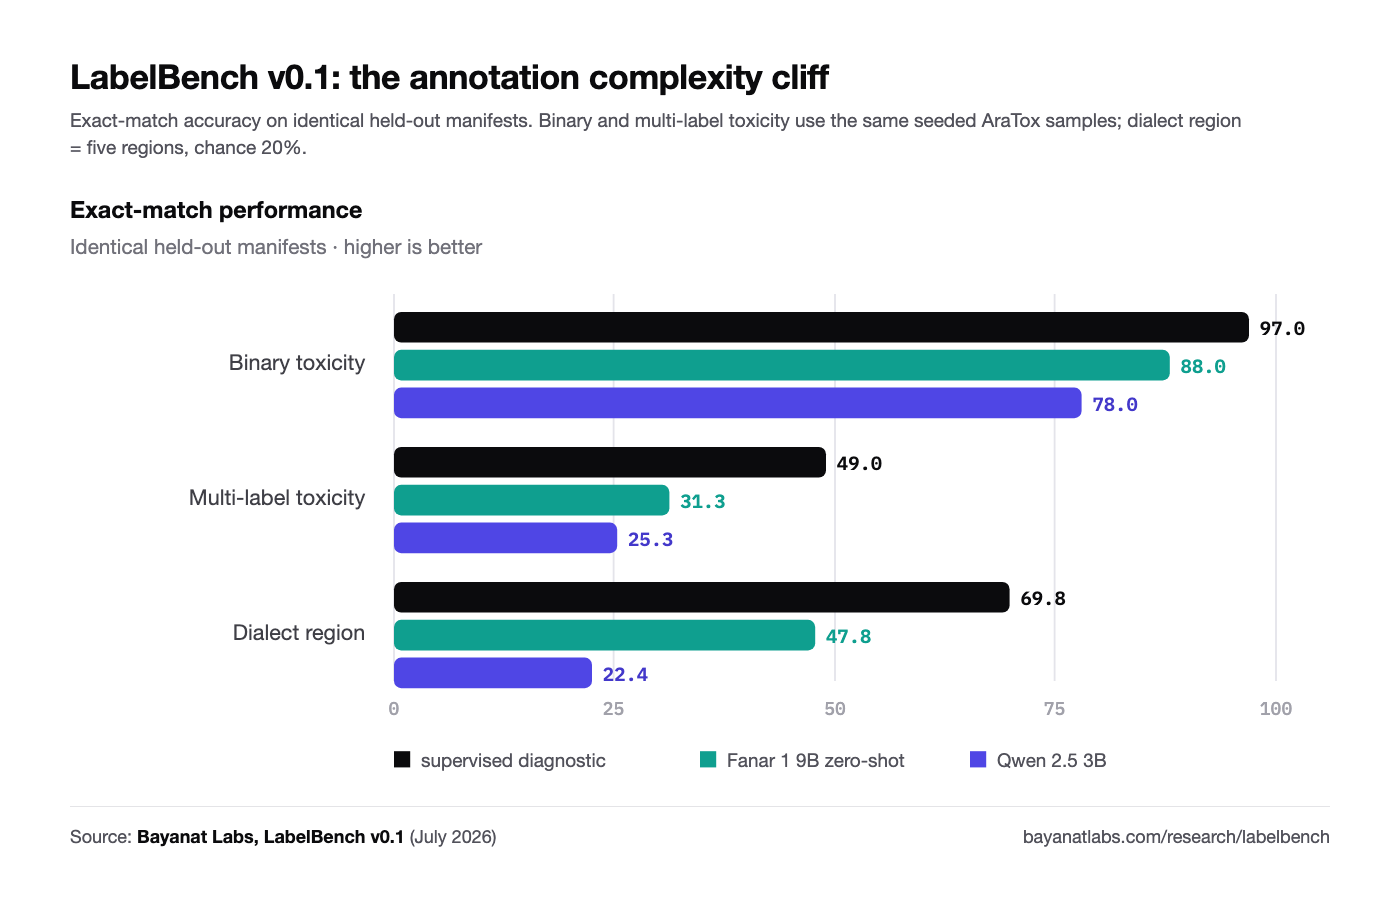
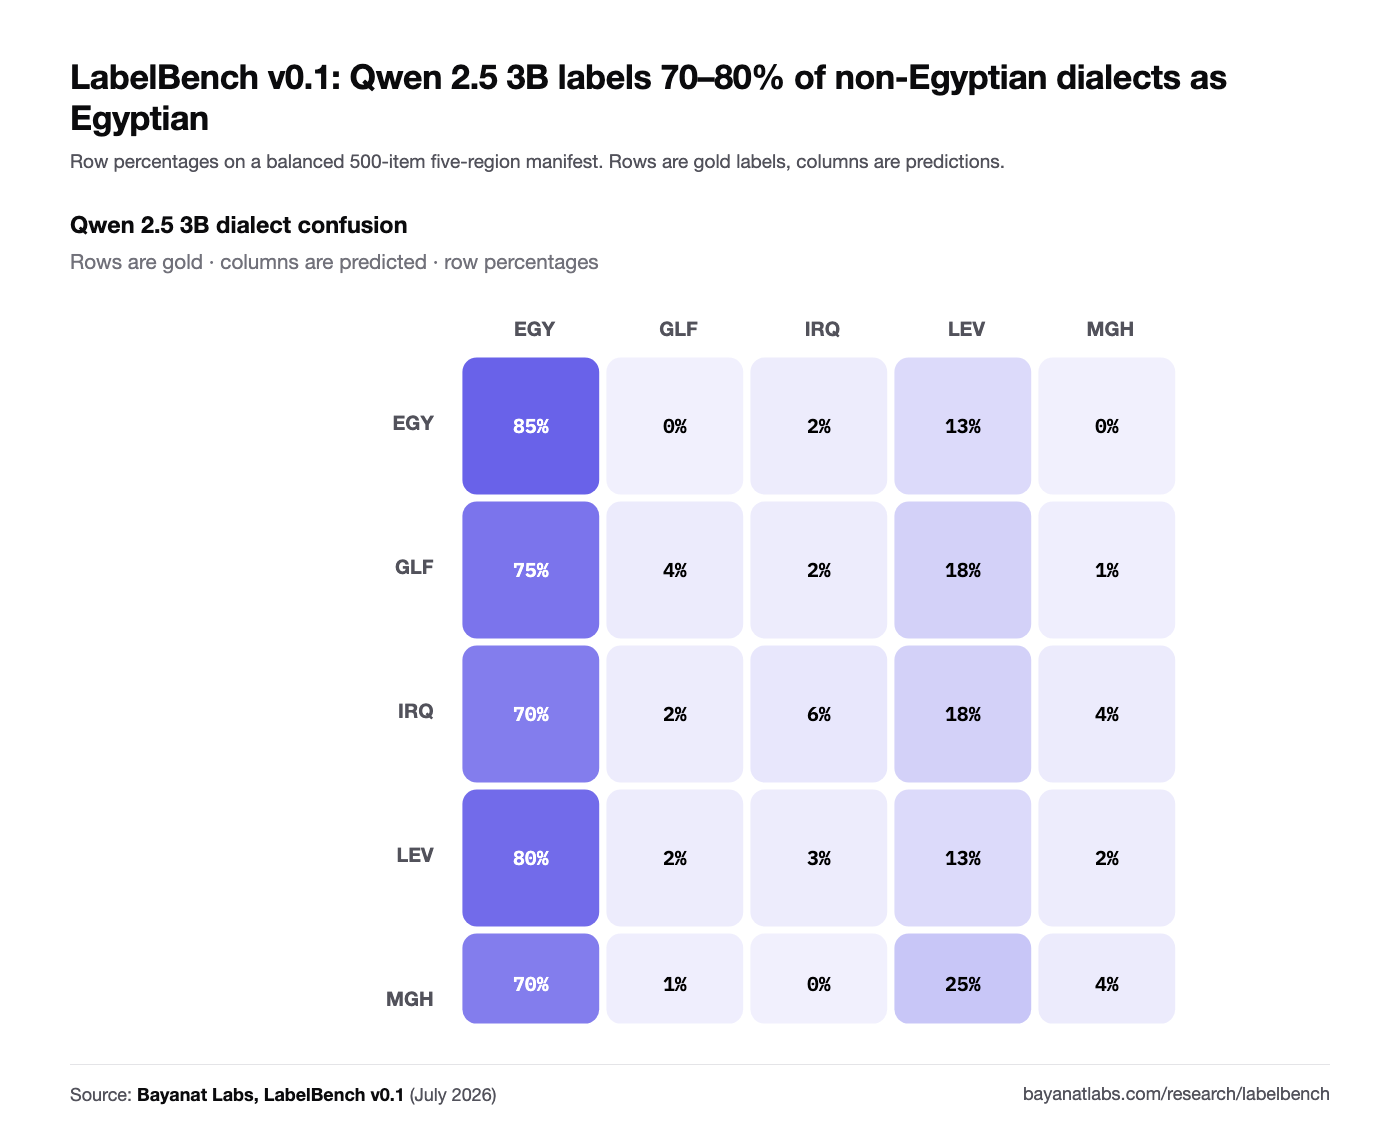
Free to use with the credit “Source: Bayanat Labs, LabelBench v0.1” and a link to bayanatlabs.com/research/labelbench.
Story angles
- Can AI replace Arabic data annotators? Why a model that looks competent on yes/no labels collapses on real annotation work.
- The dialect blind spot. Why a model can mistake Gulf, Levantine, Iraqi and Maghrebi Arabic for Egyptian, and what that means for Arabic chatbots and moderation.
- Sovereign AI needs sovereign data. Why in-region, native-speaker data and evaluation matter for Gulf AI programs. Background: PDPL and Arabic AI training data.
- The cost of Arabic in AI. The tokenization tax: why the same content can cost more to process in Arabic.
Speaking topics
For podcasts, panels and conference programmes. Talks can be given in English or Arabic.
- Arabic annotation is not binary. What LabelBench shows about AI-assisted labeling, and why Safe Automation Coverage, not average accuracy, should decide what leaves the human queue.
- A fluent answer is not a completed transaction. Evaluating Arabic agents by the state they leave behind, not by their prose: the method behind the Arabic Agent Reliability Lab (methods beta).
- Who tests the Arabic that Gulf users actually speak? How dialect-specific red-teaming and evaluation are designed and staffed. Background: Arabic red teaming.
- Beyond the leaderboard. How a bank, hospital or telco can compare Arabic models on its own traffic with a small, dialect-stratified, human-judged evaluation. Background: evaluating Arabic LLMs.
- Noisy, code-switched and on the phone. What voice-agent teams should measure per dialect and per audio condition. Background: Arabic speech data.
- From توسيم to توصيف: the language of Arabic AI procurement. Writing RFPs, contracts and job posts that are correct and findable, using the official SDAIA glossary terms. Background: دليل المصطلحات.
Logos
- Logo mark, PNG, 512×512
- Logo mark, SVG (for light backgrounds)
- Logo mark, SVG (for dark backgrounds)

Please don't recolour or stretch the mark. The wordmark is set as “Bayanat Labs”.
Contact
Interviews, data questions and corrections: hello@bayanatlabs.com. For partnerships or a pilot, use the pilot scoping form, and see how a pilot works and how we handle data.
 Bayanat Labs
© 2026 Bayanat Labs · Riyadh